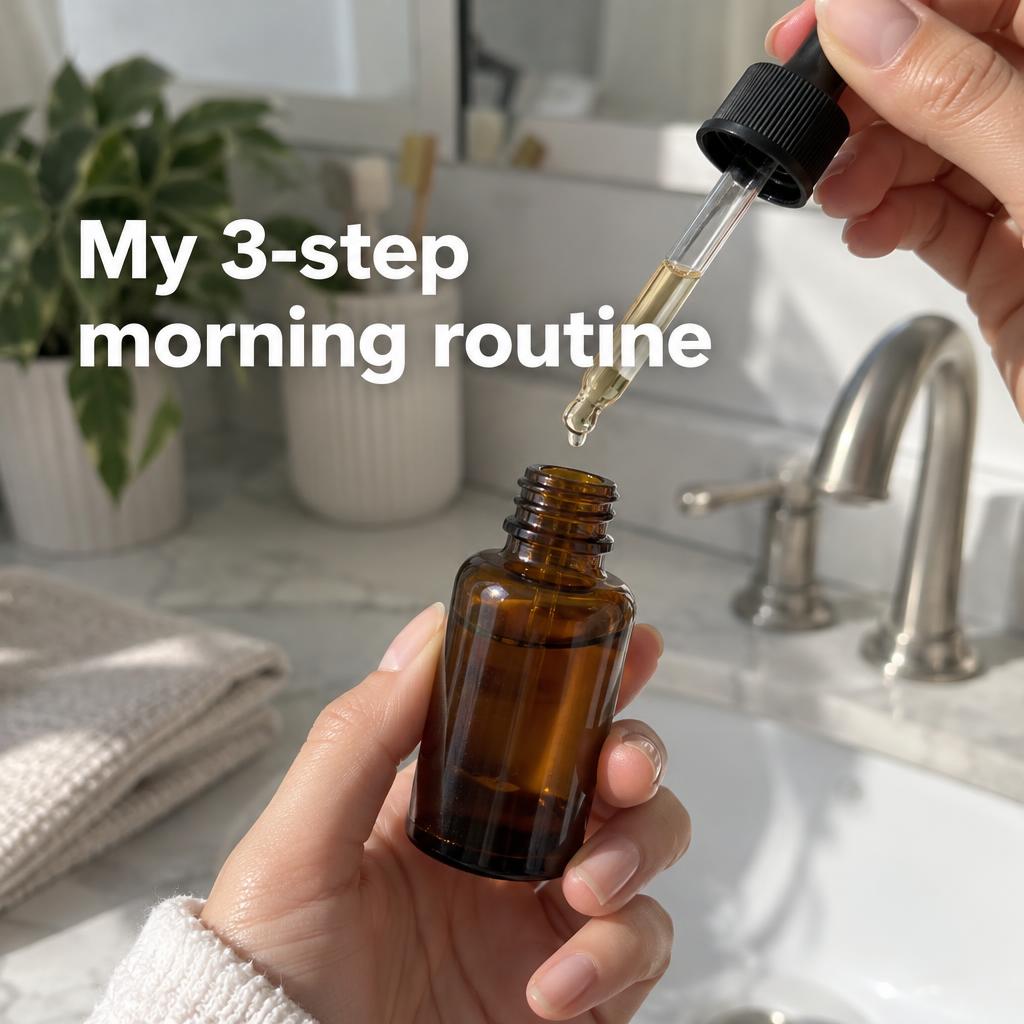
Paid social creative
Ground truth is click-through rate from a split test on live paid placements.
min. 50,000 impressions per arm, p < 0.05
Humark challenges are built from real A/B tests with significant results, so there is a right answer. The same question goes to the leading models, and your profile shows which ones you beat and where you do not.
Free to play. Verification takes three rounds.
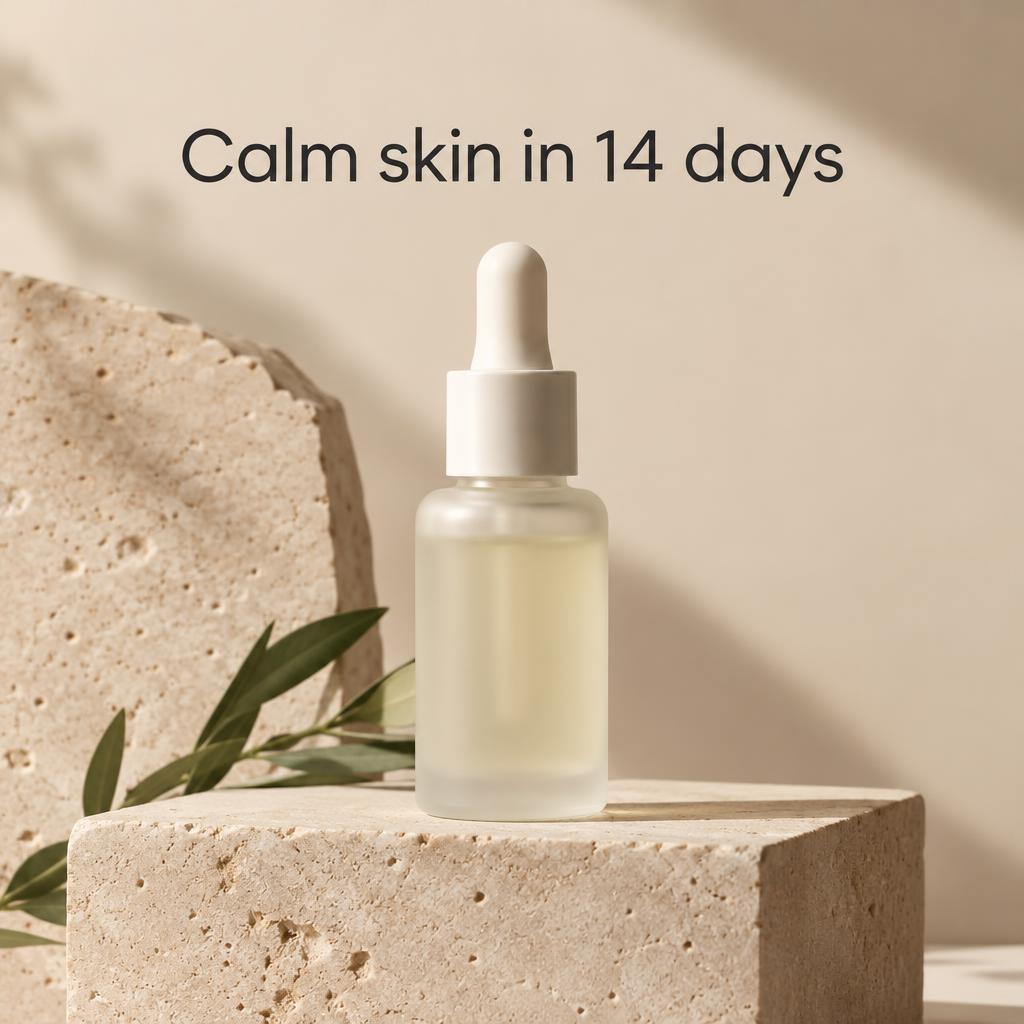
Ground truth is click-through rate from a split test on live paid placements.
min. 50,000 impressions per arm, p < 0.05
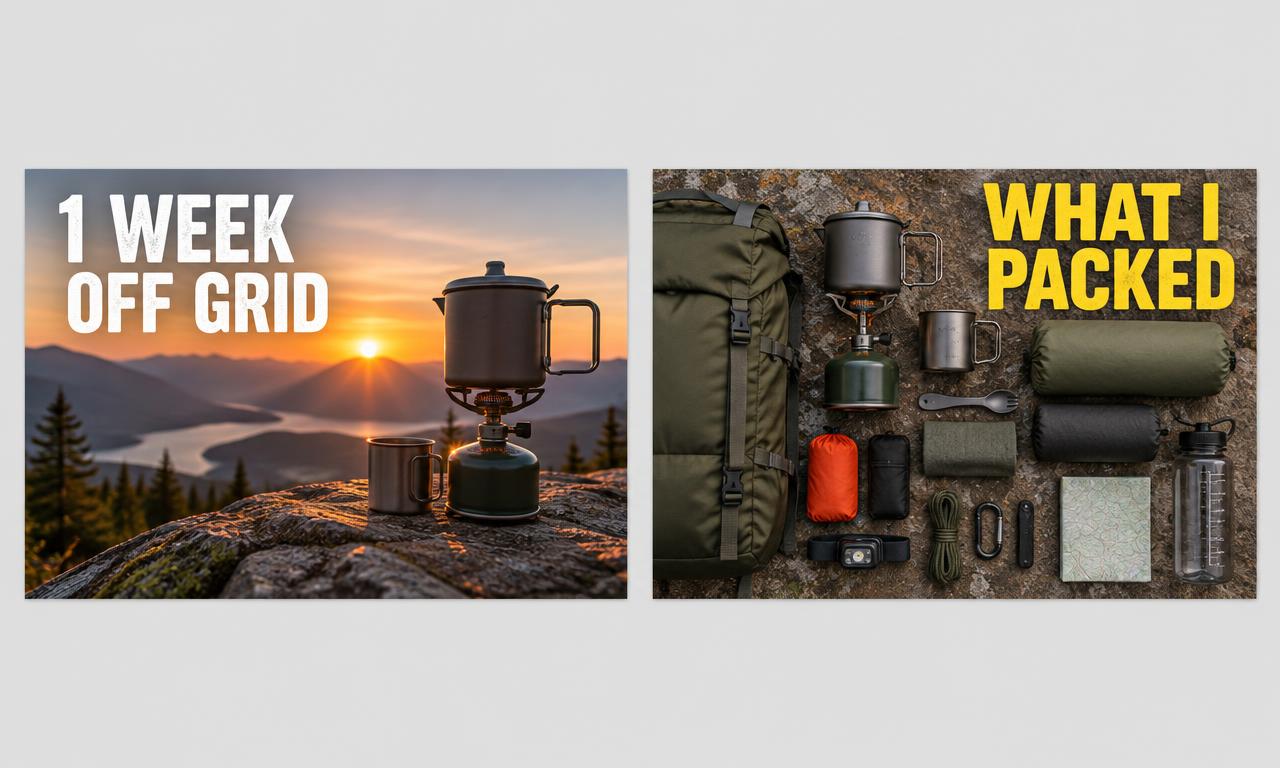
Ground truth is click-through from a thumbnail test on the same video.
min. 20,000 impressions per variant, p < 0.05
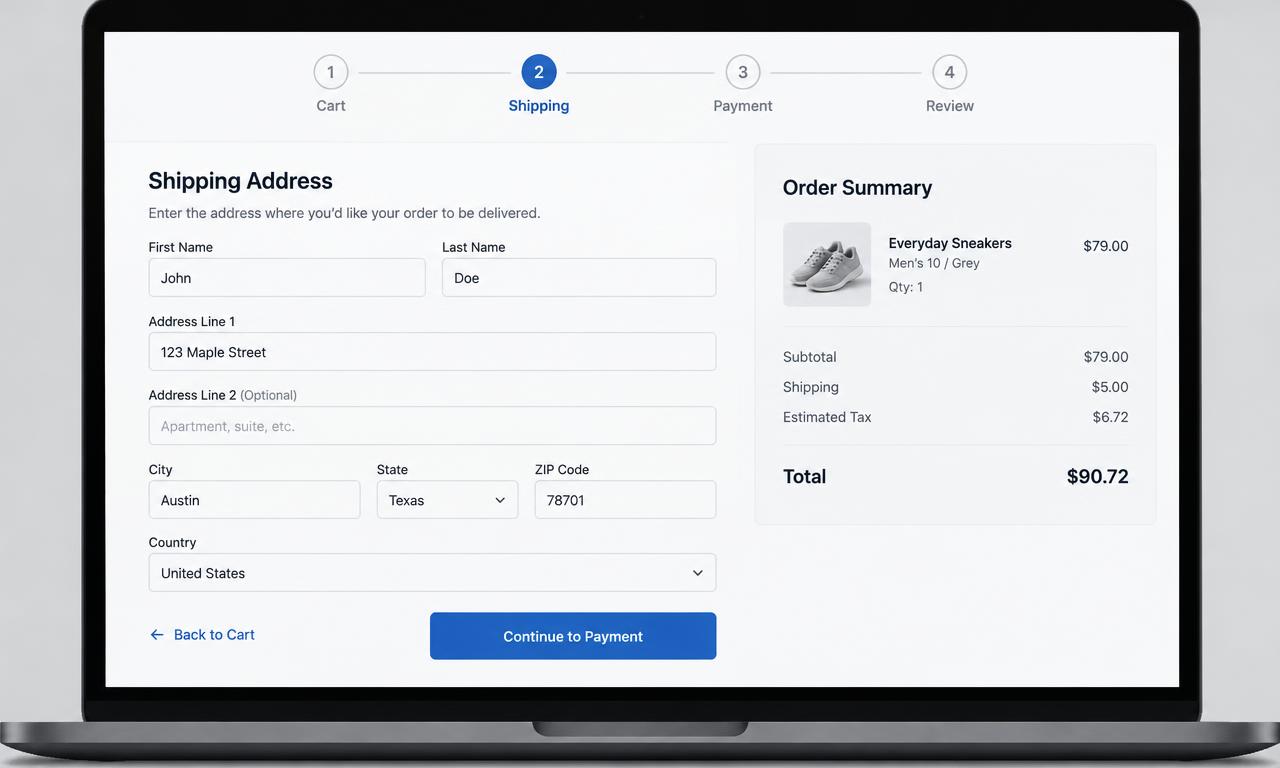
Ground truth is the step with the highest measured abandonment in funnel data.
min. 10,000 sessions, p < 0.05
If a test did not reach significance, it does not become a challenge. There is no panel of experts deciding who was right.
You
74%
31 / 42 correct
Model average
68%
same 42 challenges
Paid social creative
81%
16 challenges · ahead of all three models
Email subject lines
52%
9 challenges · behind all three models
Paid social creative
Email subject lines
Model identities are published on each challenge's result page.
You will be worse than the models at something. That is useful information and it stays on your profile.
Round 1
75%
complete
Round 2
74% running
complete
Round 3
unseen set
pending
Verification requires holding above 70% across three rounds of unseen challenges.
2%
top of the pool
~70%
held status next year
The Good Judgment Project found its superforecasters by skimming the top 2% of a large public pool, and roughly 70% of them held that status the following year. Humark works the same way. Fresh challenges, unseen, and verification only for people who hold their edge.
Source: the Good Judgment Project. External research, not Humark data.
Verified participants opt in. Recruiters search by skill and by model comparison, so a brief reads like top 1% at predicting paid social winners, beats every model tested on DTC creative. Participants are paid for their time on commissioned challenges and we take a fee from the company, never from you.
184,000 impressions. p < 0.01. Demo data.
Thirty seconds, one real test, and three models answering the same question.